
Text-to-Image · Multimodal Models · Efficient AI
Qwen-Image 2.0 vs Qwen-Image-Flash: Quality at 80 Steps vs Speed at 4
Qwen-Image 2.0 is Alibaba's full-capability image generator and editor: 1K-token instructions, native 2K, a 16x VAE. Qwen-Image-Flash distills it to 4 steps, and the recipe lets the student match its teacher.
What each model actually is
These are not two competitors. Qwen-Image 2.0 is the base system, and Qwen-Image-Flash is a distilled few-step version of it. Everything Flash does, it does by compressing the 2.0 sampling trajectory into 4 function evaluations, so the comparison that matters is: what do you lose, and what does the distillation recipe buy back?
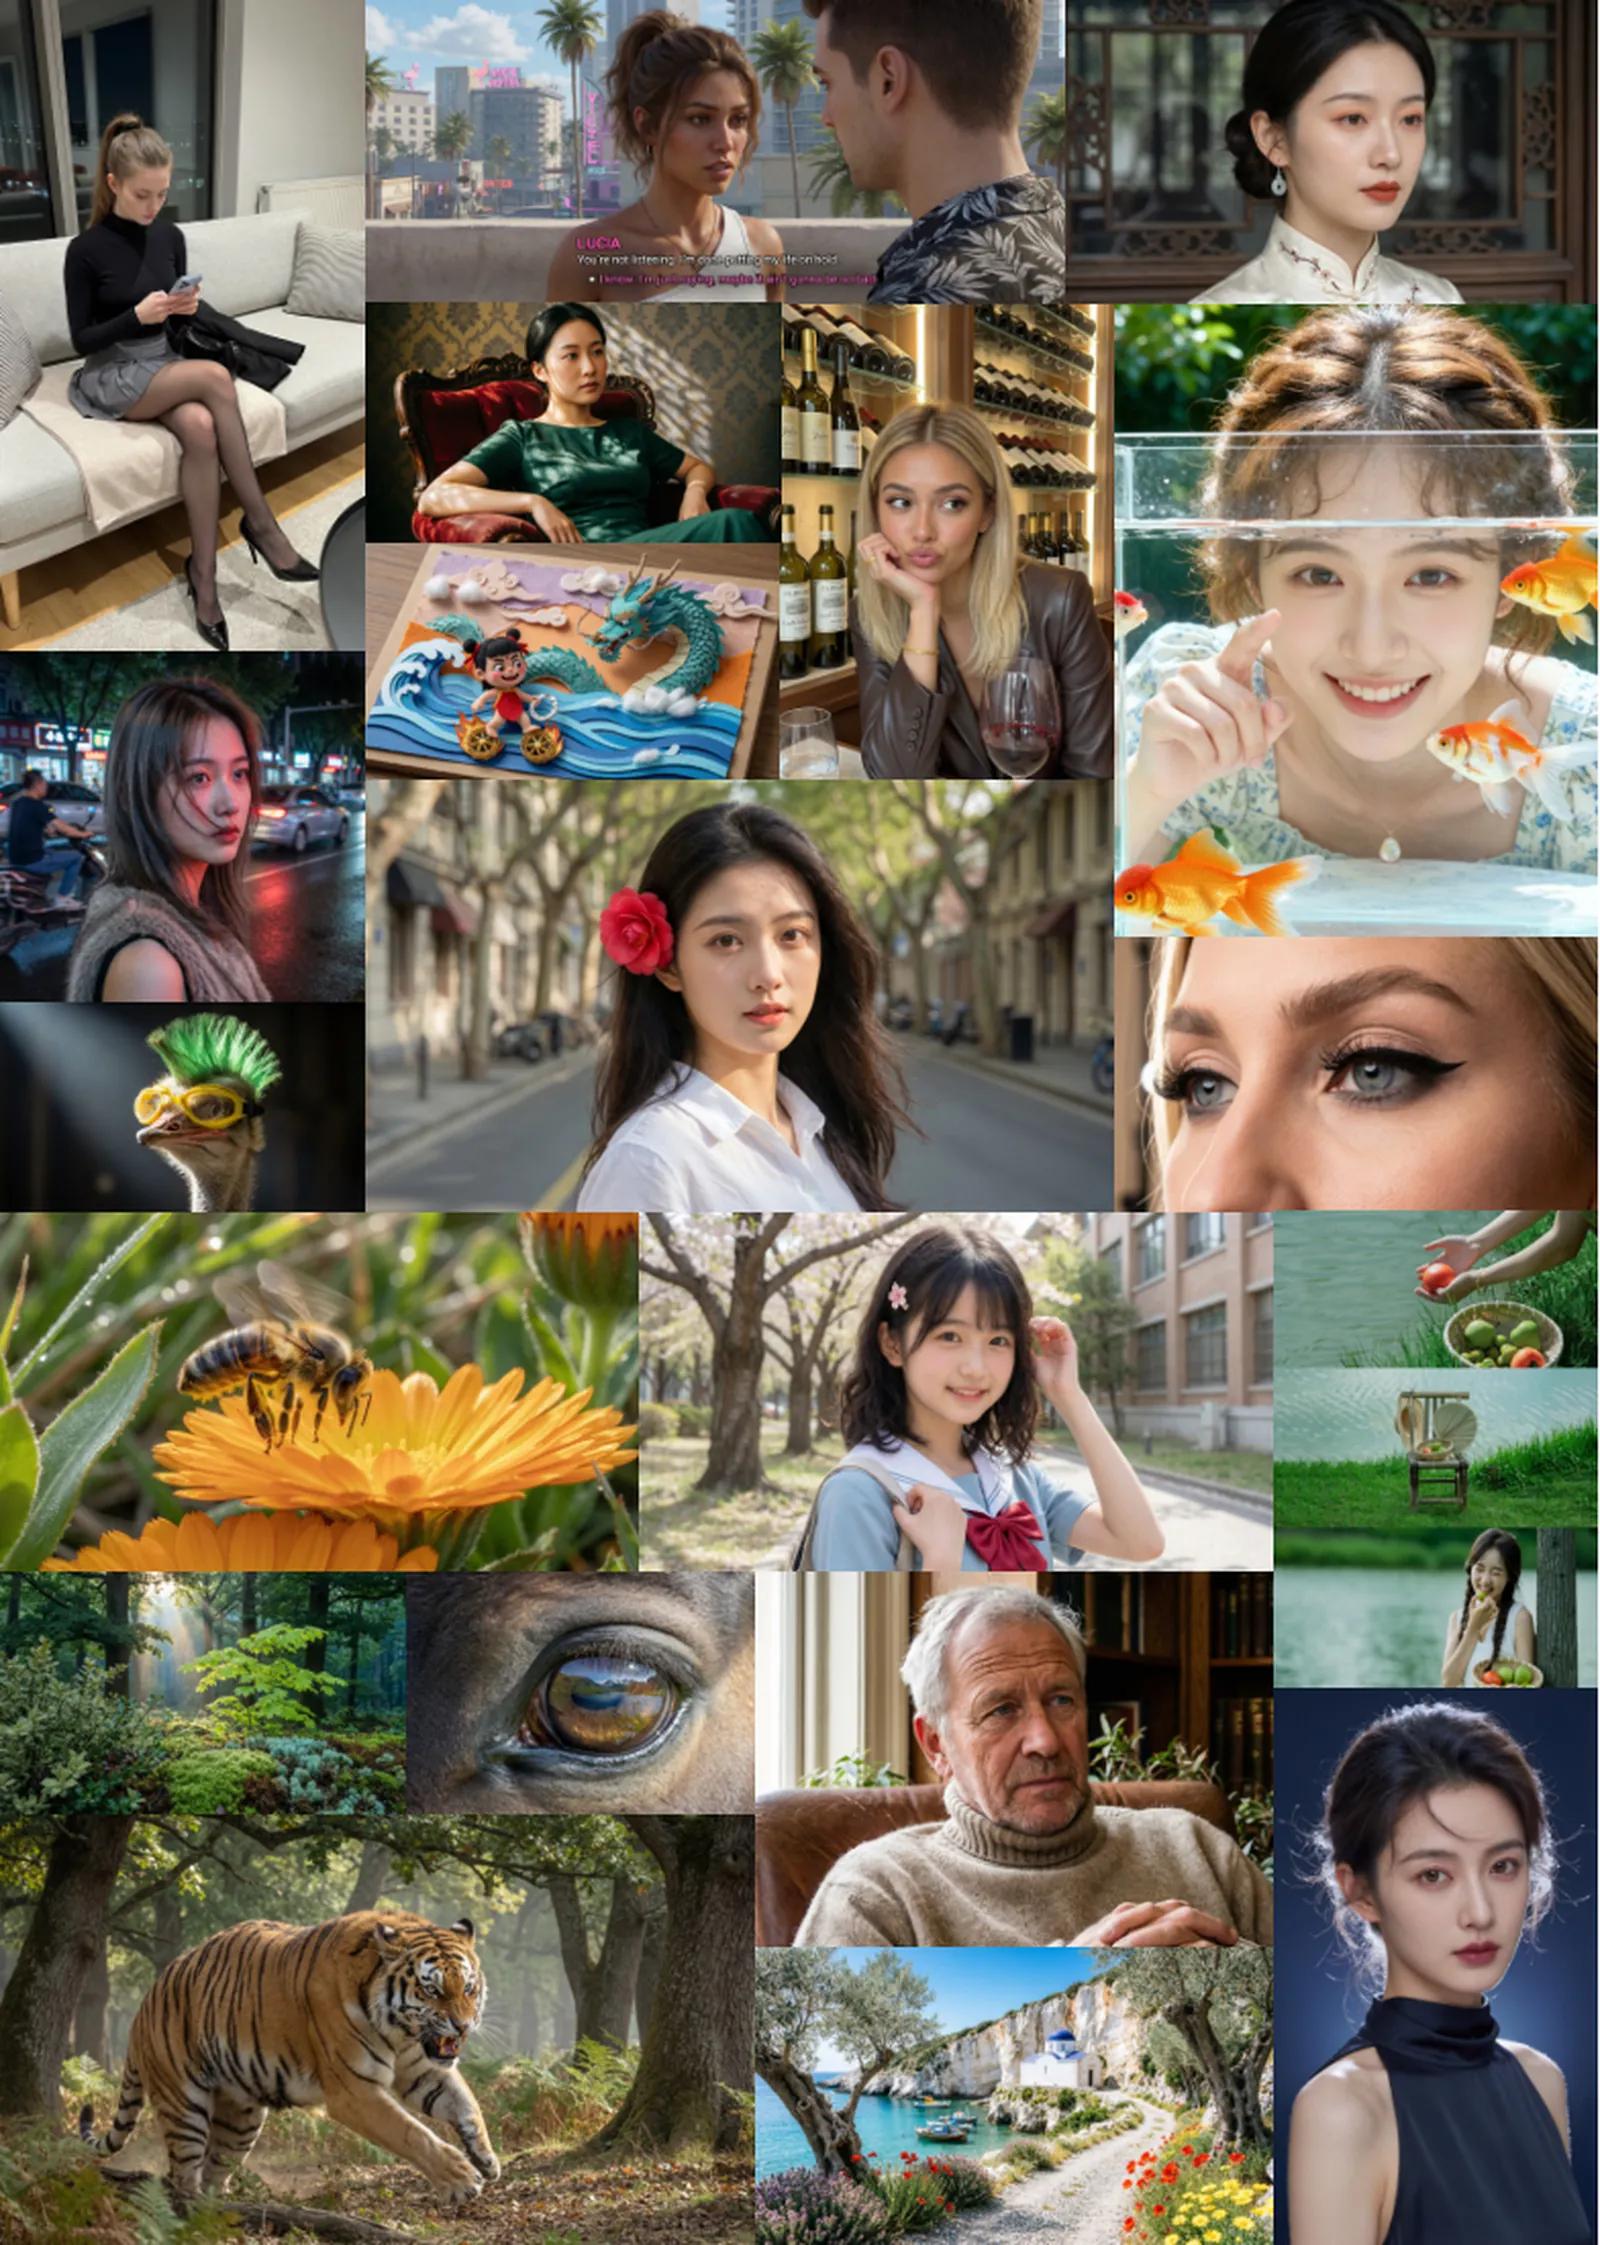
Qwen-Image 2.0 is a single Multimodal Diffusion Transformer that handles text-to-image generation and instruction-based editing in one model, conditioned by a Qwen3-VL encoder. Its pitch is capability, not speed: it follows instructions of up to 1K tokens to lay out text-dense graphics like slides, posters, infographics and comics; it generates natively at up to 2K resolution; and it runs a custom VAE with 16x spatial compression (f16c64) instead of the 8x ratio common in open-source VAEs, which is what makes native high-resolution training tractable by halving the spatial token sequence again.
This is not the first time open image generation has chased control and fidelity. ControlNet showed how to add conditional control to a frozen diffusion model, and Stable Diffusion 3 explored a different backbone family with rectified flow. Qwen-Image 2.0’s bet is doing generation and editing inside one transformer, and solving the specific failure modes that break commercial work: long text, multilingual typography, and 2K photorealism.
Qwen-Image-Flash is the deployment answer. It is distilled from 2.0 with Distribution Matching Distillation over a flow-matching backbone down to 4 NFEs, still doing both T2I and editing in one student. The paper’s real contribution is not the objective, which is standard DMD, but the recipe findings around it, and those findings change what you should expect from any few-step image model.
Key numbers
| Measurement | Qwen-Image 2.0 | Qwen-Image-Flash | Setting and source | Same harness? |
|---|---|---|---|---|
| Sampling steps | Many-step sampling (“80-NFE-style” regime) | 4 NFEs | Flash paper, T2I + editing | Yes, same model lineage |
| T2I + editing in one model | Yes | Yes (jointly distilled) | Both papers | Yes |
| T2I-Bench, portrait-only 20k distill set | Not distilled | 4.15 avg, rank #1 (GPT 5.5 judge) | 1,800-case T2I-Bench, Gemini 3.1 Pro + GPT 5.5 judges | Yes, among Flash variants |
| T2I-Bench, mixed-category 60k distill set | Not distilled | 3.62 avg, rank #4 (GPT 5.5 judge) | Same bench, more data and more diversity | Yes, among Flash variants |
| Editing-Bench, 5:5 T2I:editing mix | Not distilled | 2.97 (Gemini 3.1 Pro) / 3.41 (GPT 5.5), rank #1 | Flash task-mixture ablation | Yes, among Flash variants |
| Editing-Bench, 7:3 T2I:editing mix | Not distilled | 2.87 (Gemini) / 3.36 (GPT) | Same ablation | Yes, among Flash variants |
| T2I score after adding editing data | 2.77 / 3.28 (T2I-only student) | 2.97 / 3.41 (joint student) | Gemini / GPT judges, same student budget | Yes, paired ablation |
| Instruction length | Up to 1K tokens | Up to 1K tokens (inherits capability) | 2.0 report | n/a |
| Native resolution | Up to 2K (2048p) | Inherits 2.0 backbone | 2.0 report | n/a |
| VAE | f16c64, 16x spatial compression vs f8c16 8x | Same VAE as teacher | 2.0 report, ImageNet-1k 256x256 + text-rich corpus | n/a |
| Headline evidence | Human eval: substantially beats prior Qwen-Image on generation and editing; SOTA PSNR/SSIM among compared tokenizers at 16x | Internal preference benches vs its own teacher and ablations | Each team’s own protocol | No external head-to-head |
Read the table honestly and one asymmetry stands out. The 2.0 numbers are capability claims validated mostly by human evaluation against the team’s own prior models; the Flash numbers are controlled ablations on the same benches with VLM judges. Flash’s “matches or beats its teacher” is therefore well-supported inside its own protocol, while 2.0’s “substantially outperforms” is harder to size against external systems like FLUX or commercial generators.
What the Flash paper proves about few-step distillation
Three findings generalize beyond this model pair, and they are why the paper is worth reading even if you never deploy either model.
Data diversity can hurt. On T2I-Bench, a student distilled on 20,000 portrait-only images ranked first overall (GPT 5.5 average 4.15), while a mixed-category set three times larger, 60,000 images, ranked fourth (3.62). Worse, the mixed set lost even on text-centric prompts to the coherent single-category sets. The naive pretraining instinct, that more diverse data is better, actively degrades a distilled student.
Blend teachers step-wise, do not swap them. Directly guiding distillation with a stronger task-specialized teacher destabilized training, even though that teacher is better on its own. The working recipe keeps the pretrained base teacher as a distributional anchor and folds in the specialized teacher’s guidance selectively along the sampling trajectory. The trade-off is mild: first-step anchoring buys stability at a small cost to how much of the specialist’s distribution the student absorbs.
Editing and generation are not a zero-sum mix. With a fixed budget, a T2I-only student loses editing ability irrecoverably, but the reverse is not true: adding editing supervision raised the T2I average from 2.77 to 2.97 (Gemini judge) and 3.28 to 3.41 (GPT judge) over the T2I-only student. The balanced 5:5 mixture ranked first on Editing-Bench, ahead of 7:3. If you must pick one mixture, symmetry wins.
Limits and open questions
Qwen-Image 2.0’s own report names its weak spots: ultra-long text rendering “remains fragile,” with accuracy degrading as character counts grow and non-Latin, non-Chinese scripts struggling with correct characters, spacing and reading order; and unifying generation and editing is admitted to be “an open problem.” Its headline evidence is human evaluation, not head-to-head automated benchmarks against external systems, and parameter counts and full quantitative tables are not in the summary, so anyone benchmarking it against alternatives needs the PDF tables directly.
Qwen-Image-Flash inherits the text-rendering ceiling and adds two of its own: highly detailed tiny text and dense poster-style compositions remain hard, and some T2I outputs carry slight residual noise, most visible on clean backgrounds, because the denoising trajectory is not fully completed at 4 steps. Its scores come from preference-based VLM judges (Gemini 3.1 Pro, GPT 5.5) on internal benches, not third-party leaderboards, so cross-paper comparison is limited; and whether the single-category data finding holds beyond Qwen-Image-2.0 is untested.
When to use which
Run Qwen-Image 2.0 when the output is the product: client-facing posters, slides and comics with dense typography, 2K photoreal renders, and edits where a missed instruction is expensive. Its many-step sampling is the price of that ceiling, and its VAE compression is what keeps the high-resolution regime affordable at all.
Run Qwen-Image-Flash when latency is the product: chat UIs, bulk generation, iterative creative tools where a user waits on every call. The 4-NFE student keeps the unified T2I-plus-editing capability, and the ablations show the recipe, not luck, is carrying the quality. Budget for its failure modes: route text-dense poster jobs to the teacher, and expect occasional cleanup of residual noise on flat backgrounds.
FAQ
What is the difference between Qwen-Image 2.0 and Qwen-Image-Flash?
Qwen-Image 2.0 is the full model: many-step diffusion sampling, up to 1K-token instructions, native 2K output, 16x-compression VAE, generation and editing in one transformer. Qwen-Image-Flash is the same lineage distilled with Distribution Matching Distillation to 4 sampling steps, keeping both T2I and editing in one student for low-latency serving.
Is Qwen-Image-Flash lower quality than Qwen-Image 2.0?
Not uniformly. On the team’s internal preference benches the 4-step student matched or beat its many-step teacher on average, and adding editing data lifted T2I scores from 2.77 to 2.97 (Gemini 3.1 Pro judge). It does keep known weak spots: tiny dense text is hard, and some outputs show slight residual noise on clean backgrounds because 4 steps do not fully finish denoising.
How many sampling steps does Qwen-Image 2.0 need?
The report does not pin a single number in its summary; it operates in a many-step regime that the Flash paper characterizes as an “80-NFE-style” teacher. Flash exists precisely because that regime is too slow for interactive use, compressing it to 4 function evaluations.
Why does Qwen-Image 2.0 use a 16x VAE?
A 16x spatial compression ratio (f16c64) halves the spatial token sequence again versus the common 8x f8c16 design, which is what makes native 2K training and generation tractable. The cost is a harder fidelity-versus-diffusability trade-off, addressed with residual autoencoding and a semantic alignment loss; the report claims state-of-the-art PSNR and SSIM among compared tokenizers at that 16x ratio.
Can Qwen-Image-Flash render long text in images?
It inherits the 2.0 capability ceiling, so 1K-token instructions still work in principle, but both papers flag text rendering as the fragile axis: accuracy degrades as character counts grow, tiny dense typography remains hard for the Flash student, and scripts beyond English and Chinese struggle with correct glyphs, spacing and reading order.
One line: same model, different operating point. 2.0 buys the capability ceiling with many-step sampling; Flash buys 4-step latency and, on the team’s own benches, gives back almost nothing. Read the Qwen-Image 2.0 paper and the Qwen-Image-Flash paper on arXiv.